Research paper, 2026. Supervised by Dr. Riasat Khan, NSU.
Finding the pixels Stable Diffusion painted
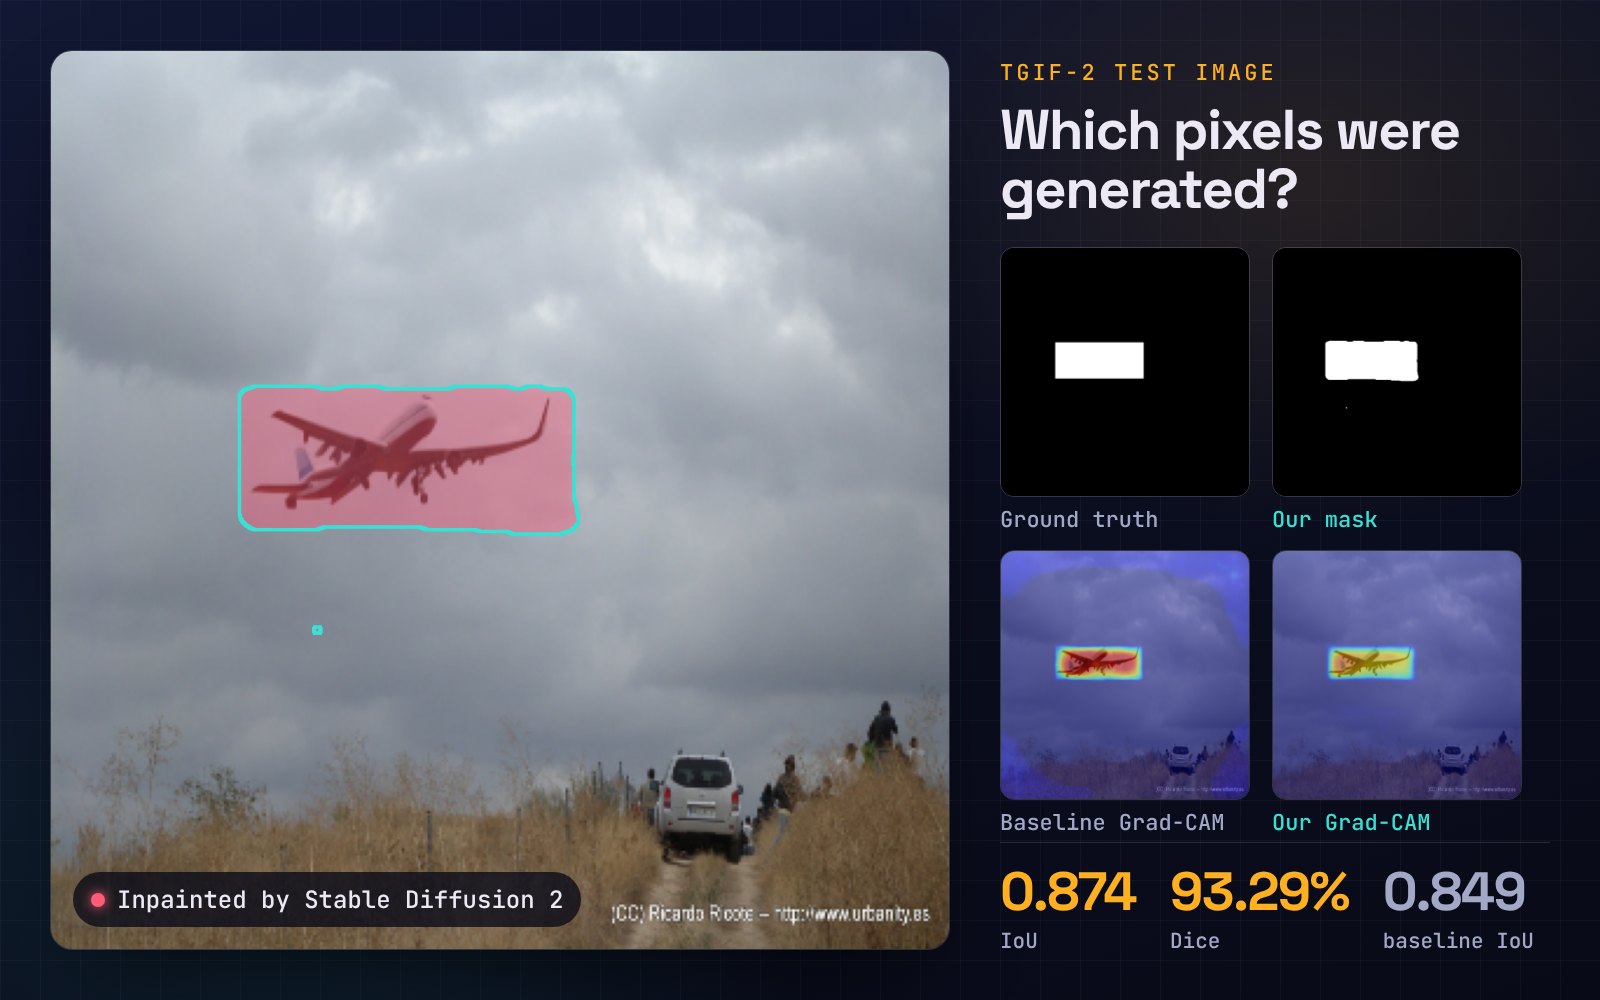
Text-guided inpainting leaves almost no visible trace. I wanted to know whether a segmentation model could mark exactly which pixels were generated, and how close it could get to the true edge.
I curated 9,611 images with pixel-level masks and kept COCO categories separate across splits so the test set couldn't leak. After benchmarking 12 segmentation models, I extended the strongest one, a ConvNeXt-L U-Net, with noise and frequency streams, edge-aware supervision and contrastive learning.
- IoU
- 0.8742 from 0.8489
- Dice
- 93.29%
- GradCAM to mask
- 0.41 to 0.79
PyTorch, ConvNeXt-L, U-Net, SRM and DCT streams, GradCAM
View code on GitHub